alexander
Your deployment passes. The containers are healthy. Then someone opens the production URL and gets a certificate error. Another user reaches yesterday’s release. A third gets nothing at all. These failures often live outside your application, where a stale DNS record or forgotten domain renewal can undo an otherwise solid release.
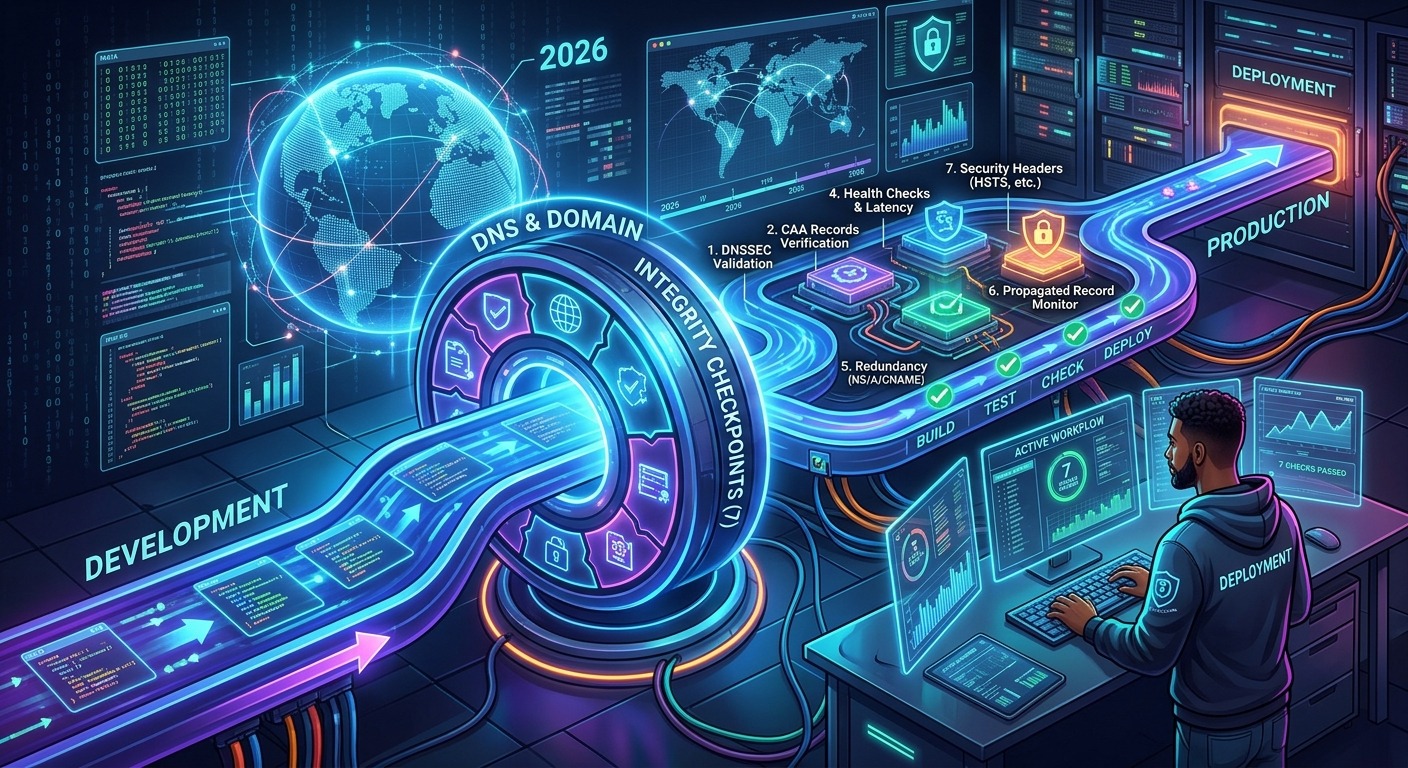
In 2026, domain and DNS checks belong beside your build, security, and integration checks. They should produce clear results, have named owners, and stop risky changes when the evidence calls for it. The seven checks below turn infrastructure assumptions into conditions your CI/CD pipeline can verify.
A healthy deployment starts before traffic reaches your application.
- Verify domain control and renewal health before depending on a hostname.
- Compare intended DNS settings with authoritative answers and resolver results.
- Test certificate readiness and real application behavior before completing a rollout.
1. Verify Domain Control and Assign an Accountable Owner
A domain appearing in your configuration does not prove your team controls it. It may belong to a former contractor, sit in a personal registrar account, or depend on credentials nobody has tested since the last migration.
Keep a domain inventory alongside your infrastructure configuration. Record the registrar, DNS provider, responsible team, recovery contact, and services that depend on each domain. Store references to credentials in your secret manager. Never store registrar passwords in the repository.
Your automated check should compare deployment hostnames with this inventory. An unknown production domain should stop the release until someone confirms its purpose and ownership. A known domain with a missing owner should create an actionable failure rather than a vague warning.
For initial onboarding or a sensitive migration, verify control with a temporary DNS TXT challenge. Generate a random token, ask the authorized operator to publish it, and verify the exact value against the authoritative DNS service. Set an expiration for the challenge and remove it afterward.
This demonstrates operational control at that moment. It does not establish legal ownership or prove that every administrator has appropriate access. Pair the technical check with account records and periodic access reviews. Avoid requiring fresh DNS writes for every routine application build.
2. Monitor Registration Expiration Before It Becomes a Release Incident
Domain registration and TLS certificates expire on separate schedules. A valid certificate cannot rescue an expired registration. Treat both as independent dependencies.
Use your registrar’s authenticated API as the main source for renewal status when one is available. Public registration data can provide another signal, but fields and availability vary across registries. A public expiration date may also need interpretation during renewal processing.
Set explicit thresholds that match your purchasing process. For example, open an operational ticket when a production domain has fewer than 60 days remaining. Escalate below 30 days. Consider blocking changes to that domain below 14 days unless an approved incident procedure applies. These are team policies, so adjust them to your renewal lead time.
Check more than the date. Confirm that automatic renewal is enabled where intended, payment details are current, and renewal notices reach a monitored address. Automatic renewal is a setting, not proof that the next payment will succeed.
Run this check daily and publish a timestamped result that deployment jobs can read. If the registrar API fails, report an unknown status. Do not silently turn an unavailable response into a healthy result. Decide how long cached evidence remains acceptable before it needs human attention.
3. Compare DNS Records With the Intended Configuration
A DNS lookup that returns an address can still return the wrong address. Your pipeline needs an expected result, ideally defined through infrastructure as code, and a comparison that understands your hosting setup.
Check A and AAAA records independently. A correct IPv4 destination can hide a stale IPv6 destination, leaving part of your audience on a broken path. Check CNAME targets for hostnames that use aliases. Protect MX and required TXT records when changing a shared zone, even if the release only affects the website.
Start with small diagnostic commands:
dig +noall +answer app.example.com A
dig +noall +answer app.example.com AAAA
dig +noall +answer app.example.com CNAME
For enforcement, parse response status, record type, and returned values rather than treating any output as success. Normalize trailing dots and sort unordered record sets before comparing them. A harmless ordering change should not break a deployment.
CDNs and managed platforms may return changing addresses. In those cases, validate the configured alias or provider resource through its API, then test the public endpoint separately. Hardcoding today’s CDN addresses creates brittle checks that fail during normal platform operation.
Make drift reports specific. Name the hostname, expected configuration, observed result, and source of the observation. That gives the engineer enough information to act without repeating the entire investigation.
4. Investigate Unfamiliar Domains Before Connecting Services
A new webhook destination, authentication callback, or customer domain can introduce infrastructure your team has never reviewed. Before configuring that connection, establish who supplied the hostname and what role it will play.
Use domain research as a starting resource when investigating unfamiliar domains before configuring integrations or troubleshooting deployment issues. Correlate your findings with the vendor’s verified documentation, your internal inventory, and confirmation through an established contact channel.
Public registration details may be limited or privacy protected. A recently registered domain is not automatically malicious. An older domain is not automatically trustworthy. Treat research as context for a decision, not an authorization signal.
Automate the parts that have clear rules. Compare proposed integration destinations with approved domains. Flag unexpected hostname changes in configuration reviews. Require an owner and purpose for each new external destination.
Check abandoned service references as part of the same process. A CNAME pointing to a removed hosting resource deserves investigation. Whether another party can claim that destination depends on the provider’s controls. Report the dangling reference without claiming a takeover is possible until that condition has been verified.
5. Check Delegation and Cache Behavior Before a Cutover
Your DNS provider can show the correct record while users still receive an older answer. Separate two questions: whether authoritative servers have the intended data, and whether recursive resolvers have refreshed their cached answers.
Query each authoritative nameserver directly and compare the relevant records. Check parent delegation when moving DNS providers. A correctly configured zone does little good if the parent still directs queries to the previous nameservers.
The DNS specification in RFC 1035 defines TTL as the interval during which a resource record may be cached before its source should be consulted again. Lowering a TTL does not erase copies already cached under the previous value. Make planned TTL changes early enough for that earlier interval to pass.
Also account for negative caching. If a hostname did not exist before the release, some resolvers may temporarily retain that absence. Publishing the record does not guarantee that every client immediately receives it.
Use bounded retries with clear deadlines. Probe representative recursive resolvers and, where relevant, your organization’s internal resolver. Record which resolver returned each answer. A mismatch should identify a specific observation rather than produce a generic “DNS propagation failed” message.
If DNSSEC is enabled, include validation in your checks. During a provider migration, mismatched parent DS records and zone signing data can break resolution for validating clients. Treat signing and delegation changes as coordinated infrastructure work.
6. Validate TLS Issuance and Renewal Before Routing Traffic
A hostname resolving correctly does not mean its HTTPS endpoint is ready. Verify certificate trust, hostname coverage, expiration, and the certificate chain presented by the actual listener.
Test with the intended hostname so the request includes the correct Server Name Indication. Connecting directly to an IP address without the hostname can reach a default virtual host and give you a misleading result.
Before a cutover, use a command that preserves the hostname while selecting the candidate address:
curl --fail --silent --show-error \
  --connect-timeout 5 \
  --max-time 15 \
  --resolve app.example.com:443:203.0.113.10 \
  https://app.example.com/health
Replace the example hostname and documentation address with your candidate endpoint. Keep certificate verification enabled. A successful request with verification disabled does not establish TLS readiness.
Check the issuance path as well. The HTTP-01 challenge described in ACME certificate documentation uses port 80, so redirects, firewall rules, and routing must permit validation. DNS-01 requires the expected TXT record under the challenge name and can support wildcard issuance.
Inspect applicable CAA records for restrictions that could prevent issuance. Use narrowly scoped DNS credentials for automated challenges. Exercise renewal through a supported staging environment or dry-run mechanism rather than repeatedly requesting production certificates during builds.
Set renewal alerts according to certificate lifetime and your recovery window. Alert on failed renewal attempts while there is still time to fix the underlying problem.
7. Probe the Public Deployment and Keep Recovery Checks Ready
The final check should follow the path your users take. Make a request through public DNS, complete a verified TLS connection, and confirm that the expected application answers.
A generic HTTP 200 is weak evidence. It might come from a default backend, maintenance page, or previous release. Check a stable response field or release identifier that confirms which deployment served the request. Keep the health response free of secrets.
Test redirects deliberately. A site that loads at one hostname may loop when accessed through another. Validate supported entry points, including the root domain and the preferred application hostname when both are part of your service.
Check IPv4 and IPv6 paths from runners that support them. For internal applications, run an additional probe from the network where users actually connect. A public runner cannot verify a private DNS view or an internal routing path.
Keep the previous origin available during a planned cutover. Reverting a DNS record does not immediately move every client back because cached answers can persist. Recovery must account for traffic reaching both destinations during the transition.
Save probe results with the deployment record. Include timestamps, resolved addresses, certificate expiry, release identity, and failure reasons. Redact credentials and tokens before uploading logs.
Make the Next Release Prove Its Route
These checks work best when they run at different points instead of making every build wait for every external service. Give each result an owner, a freshness limit, and a defined consequence.
- Before merging, validate the domain inventory and review intended DNS changes.
- Before shifting traffic, confirm authoritative records, candidate endpoint health, and TLS readiness.
- After deployment and on a schedule, probe public behavior, renewal health, and configuration drift.
Start with the failure your team has already experienced. If stale records caused the last incident, automate record comparisons first. If renewal ownership is unclear, fix the inventory and alerts before adding more deployment logic.
A useful check gives the engineer a clear next action. It says which hostname failed, what was expected, what happened, and who can resolve it. Build that clarity into the workflow, and domain problems become easier to catch before customers find them.