alexander
You have a production bug. The error logs are useless. You add a console.log, redeploy, wait, and still see nothing helpful. Then you add another log. Then another. Hours later, you find the culprit was a null pointer in a code path you swore was covered. This cycle is exhausting.
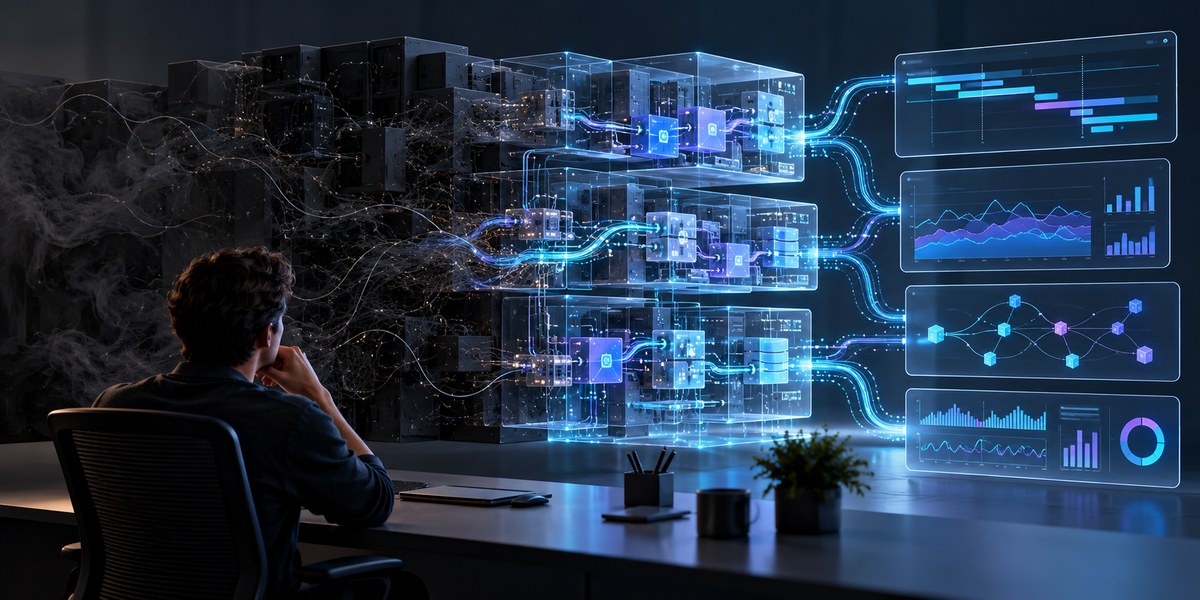
Observability tools for debugging change that pattern entirely. Instead of guessing what your code is doing, you get real time data on every function call, every database query, and every slow endpoint. You stop fixing symptoms and start fixing root causes.
Observability turns your application into a transparent system. By combining structured logs, real time metrics, and distributed traces, you can pinpoint failures in seconds instead of hours. This guide covers the three pillars of observability, a practical five step process for debugging any issue, and the common mistakes that keep teams stuck in the dark. You will learn which tools to use and how to interpret their signals without getting overwhelmed.
Why traditional debugging falls short
Print statements and basic log files only work when you already know where to look. In a modern microservices architecture, a single user request can travel through ten different services. If one of them fails silently, you have no way to connect the dots.
Traditional debugging assumes you can reproduce the bug locally. But race conditions, memory leaks, and timing issues often only appear under production load. You need a system that captures what happened across the entire stack at the moment of failure.
Observability tools for debugging solve this by treating your application as a data source. Every request, error, and performance anomaly becomes a data point you can query after the fact.
The three pillars of observability
To see inside your code, you need three types of data. Each one answers a different question.
| Pillar | Question it answers | Example tool |
|---|---|---|
| Logs | What happened? | Structured logging with JSON output |
| Metrics | How many times did it happen? | Prometheus, Datadog |
| Traces | Why did it happen in this order? | Jaeger, OpenTelemetry |
Logs give you the raw events. Metrics give you the big picture. Traces connect the dots across services. When you combine all three, you get a complete picture of any incident.
Logs: Your first line of defense
Structured logs are the foundation of any observability strategy. Instead of writing logger.info("User logged in"), you send a JSON object with user ID, session duration, and browser type. This makes your logs searchable and filterable.
Most teams start with logs because they are the easiest to implement. But logs alone are not enough. They lack context about how a request moved through your system. That is where traces come in.
Metrics: The big picture
Metrics tell you if something is trending in the wrong direction. A sudden spike in 500 errors or a drop in checkout completions signals a problem before your users complain.
Modern observability tools for debugging let you set up dashboards that refresh in real time. You can see CPU usage, database connection pool size, and request latency all in one place. When something looks off, you drill into the traces to find the specific request that caused it.
Traces: The detective work
Distributed tracing is the most powerful tool for debugging complex systems. It follows a single request from the edge of your network all the way through every service, database call, and cache hit.
For example, if your checkout page takes five seconds to load, a trace shows you that 4.5 seconds were spent in a third party payment gateway. Without a trace, you would have spent hours blaming your own code.
A five step process to debug with observability
Here is a repeatable process you can use the next time something breaks.
- Check your metrics dashboard first. Look for anomalies in error rates, latency, or throughput. This tells you which service or endpoint is affected.
- Query your logs for the time window. Use a structured query to find all events related to the failing endpoint. Filter by user ID or request ID if you have one.
- Open the trace for a single failing request. Look at the span list to see which step took the longest or returned an error.
- Identify the root cause span. This is the span that returned an error code or took an abnormally long time. Click into it to see the error message and stack trace.
- Fix the code and verify with a new trace. After deploying the fix, run the same request and confirm the trace shows a clean path.
This process works for latency issues, crashes, and silent failures. The key is always starting with the metric or trace, not blindly reading logs.
Common mistakes that keep you in the dark
Even with great tools, teams make errors that reduce observability to noise. Here are the most common ones.
- Logging too much. If every function call writes a log, you drown in data. Log only meaningful events: errors, state transitions, and external calls.
- Ignoring trace sampling. Traces are expensive. Sample 1% to 10% of requests in production. You will still catch most issues without the performance cost.
- Not correlating logs with traces. Every log entry should include a trace ID. Otherwise you cannot connect a log to the request that triggered it.
- Only looking at averages. Average latency hides outliers. Track p99 and p99.9 latency to catch the slow requests that frustrate users.
“Observability is not about having more data. It is about asking the right questions of the data you already have.” — Charity Majors, co-founder of Honeycomb
Tools worth trying in 2026
The observability landscape has matured. You no longer need to build your own system from scratch.
For open source, the OpenTelemetry standard is now the default way to instrument your code. It works with any language and sends data to any backend. Pair it with Jaeger for traces and Prometheus for metrics.
For a hosted solution, Datadog and Honeycomb offer full observability platforms with AI driven anomaly detection. They are expensive but save engineering time when you are debugging a production incident.
If you want something lightweight for a smaller project, check out 9 web app debugging tools worth adding to your developer toolkit in 2026. Many of them include built in observability features.
How to get started today
You do not need to instrument your entire system at once. Start with one service or one endpoint.
First, add structured logging. Replace console.log with a JSON logger that includes a request ID. Second, install an OpenTelemetry SDK in your main application. It will automatically collect traces for HTTP requests and database calls. Third, set up a simple dashboard with three metrics: error rate, p99 latency, and throughput.
Once you see the data flowing, you will wonder how you ever debugged without it.
For a broader look at modern development practices, read our guide on essential dev tools for streamlining your development workflow in 2026. Observability fits naturally into a toolchain that also includes CI/CD, feature flags, and automated testing.
See your code, not your guesses
Observability tools for debugging remove the mystery from software failures. When you have logs, metrics, and traces working together, you spend less time guessing and more time fixing. The next time an alert fires at 2 AM, you can pull up a trace, find the exact line of code that failed, and deploy a fix before your users even notice.
Stop debugging in the dark. Instrument your code, trust your data, and let observability show you what is really happening inside your application.