alexander
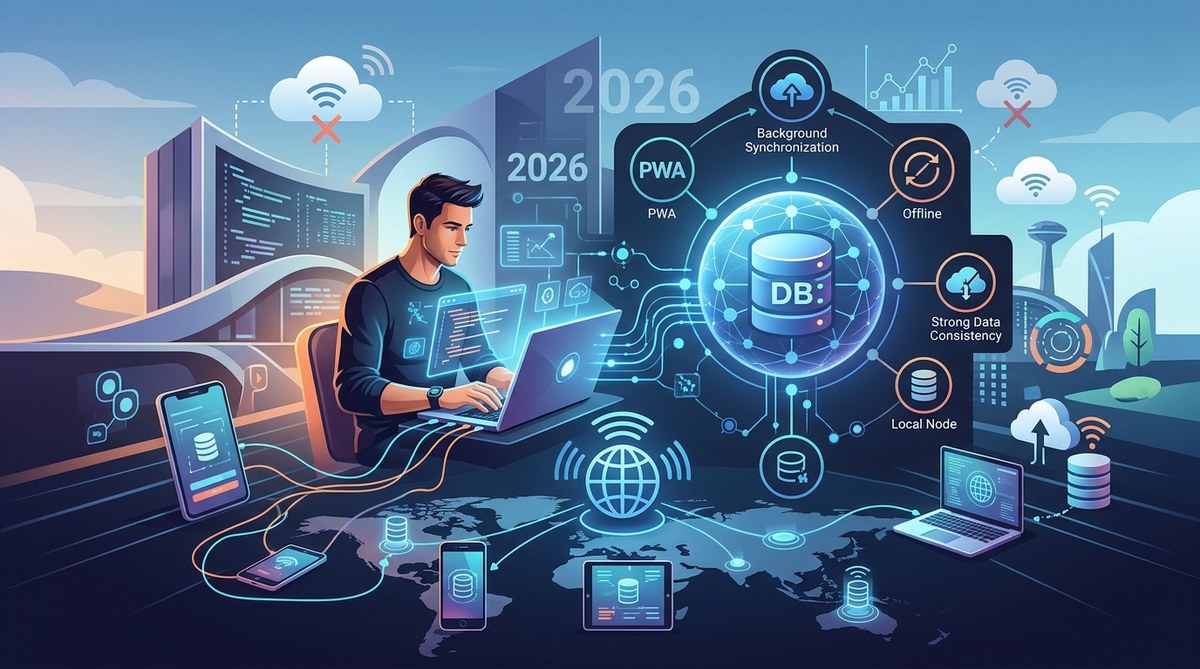
Building software that works without a network connection isn’t just a nice feature anymore. It’s a fundamental shift in how we think about data ownership and user experience. Users expect their apps to be responsive whether they’re in a subway tunnel, on a flight, or dealing with a spotty cell signal. An offline-first architecture guide helps you design systems where the local device is the primary source of truth, and the server is a synchronization peer rather than a gatekeeper. This approach reduces latency, improves privacy, and gives users control even when the internet disappears.
Offline-first architecture flips the traditional client-server model by treating the local database as the authoritative source. This guide covers core sync strategies, conflict resolution patterns, and the tools you need to build apps that work reliably without connectivity. You will learn practical steps for schema design, change tracking, and merging data across devices while avoiding common pitfalls that break offline experiences.
Why Offline-First Matters More in 2026
The assumption that every user has a stable internet connection is outdated. Rural areas, international travel, and even urban dead zones make continuous connectivity unreliable. Beyond connectivity, users are becoming more privacy-conscious. Storing data locally first means sensitive information never touches a remote server unless the user chooses to sync. Applications like note-taking tools, field service apps, and collaborative document editors now compete on how well they handle offline scenarios. If your app freezes or loses data when the network drops, users will find an alternative.
Core Principles of Offline-First Design
Before picking a database or sync engine, you need to understand the foundational ideas that make offline-first work.
Local Data is the Source of Truth
In a traditional online-first app, the server validates every write. In an offline-first app, the local client accepts writes immediately and syncs them later. This means your local database must support the same data integrity rules you would enforce on the server. Constraints, unique indexes, and foreign keys all need to work locally.
Conflict Resolution is Inevitable
When two users edit the same record while offline, you will have conflicts. Your architecture must define how to merge, discard, or flag conflicting changes. Common strategies include last-writer-wins, CRDTs (Conflict-Free Replicated Data Types), and custom merge functions.
Sync is Asynchronous and Idempotent
Synchronization should run in the background without blocking the user interface. Every sync operation must be idempotent, meaning running it multiple times produces the same result. This protects against network retries and partial failures.
Choosing the Right Local-First Database
Your choice of local database determines how much control you have over sync, conflict resolution, and performance. Here is a comparison of popular options in 2026.
| Database | Sync Strategy | Best For |
|---|---|---|
| SQLite (via extensions like Litestream) | Write-ahead log replication | Mobile apps, embedded systems |
| FoundationDB | Distributed transactions | Enterprise, high-consistency needs |
| CouchDB / PouchDB | Multi-master replication with MVCC | Web apps, offline-first web UIs |
| Firebase Firestore (offline mode) | Last-writer-wins per field | Prototyping, small teams |
| ObjectBox | Offline-first by design, sync via ObjectBox Sync | IoT, mobile, desktop apps |
Each option has trade-offs. SQLite with Litestream gives you fine-grained control but requires more manual sync logic. PouchDB syncs directly with CouchDB and handles conflicts out of the box but may not scale to millions of records on a single device.
A Practical Sync Strategy in 5 Steps
Building a robust sync mechanism requires a clear process. Here is a step-by-step approach you can adapt to your stack.
- Assign global unique identifiers (UUIDs) to every record. Do not use auto-increment IDs. UUIDs prevent collisions when records are created on different devices without a central server.
- Track changes with a version vector or timestamp. Each record needs a field like
updated_ator a Lamport clock value. When syncing, the client sends only records that changed since the last sync. - Implement a write-ahead log for offline operations. Every local write should go into a queue. The queue records the operation type, the record ID, the new data, and a sequence number. This log ensures no writes are lost.
- Sync in batches with exponential backoff. When the network becomes available, push the write-ahead log to the server in small batches. If a batch fails, wait and retry with an increasing delay.
- Apply server responses to the local database. After the server confirms a batch, update the local version vectors and clear the corresponding entries from the write-ahead log.
Common Mistakes and How to Avoid Them
Even experienced developers make errors when designing offline-first systems. This table outlines frequent pitfalls and their solutions.
| Mistake | Consequence | Fix |
|---|---|---|
| Using auto-increment IDs | ID collisions on sync | Switch to UUID v7 or ULIDs |
| Ignoring clock skew | Wrong conflict resolution | Use vector clocks or hybrid logical clocks |
| Syncing full database on every reconnect | High bandwidth and battery drain | Sync only delta changes since last sync |
| Not handling partial sync failures | Duplicate or missing records | Make sync operations idempotent; use operation IDs |
| Assuming all conflicts are resolvable automatically | Data loss or silent corruption | Surface conflicts to the user with a merge UI |
Expert advice: “Start with a simple last-writer-wins strategy. It handles 80% of conflicts without complexity. Only add CRDTs or custom merge functions when you have real data showing that users are losing work.” — Senior engineer at a major note-taking app
Tools That Simplify Offline-First Development
You don’t need to build everything from scratch. Several frameworks and libraries handle the heavy lifting of sync and conflict resolution.
- PouchDB: A JavaScript database that syncs with CouchDB. It runs in the browser and on Node.js. Perfect for web apps that need offline support without a heavy backend.
- RxDB: A reactive database for Node.js and JavaScript. It supports replication with CouchDB and has built-in conflict handlers. It also supports encryption for local data.
- SQLite with Litestream: Litestream streams SQLite write-ahead logs to S3 or any object store. This gives you a replicable database file without custom sync code.
- Ditto: A framework for building local-first apps using SQLite and a custom sync protocol. It handles conflict resolution and peer-to-peer sync out of the box.
- TinyBase: A document-oriented database for JavaScript that supports offline-first patterns. It is lightweight and works well for single-user apps or small teams.
For a broader look at what is available, check out our ultimate guide to modern dev tools for accelerating software development. It covers runtime environments, debuggers, and databases that complement an offline-first stack.
Designing Your Data Model for Offline Sync
Your schema design has a massive impact on how well sync works. Follow these guidelines.
- Use separate tables for user-generated data and system metadata. Metadata like sync timestamps and device IDs should not clutter the main data tables.
- Store deleted records as tombstones. When a user deletes a record, mark it as deleted with a timestamp. Do not physically remove it until all devices have acknowledged the deletion.
- Avoid complex joins in local queries. Joins across multiple tables can become expensive on mobile devices. Denormalize where it makes sense to keep reads fast.
- Keep blob storage separate. Large files like images or videos should be stored outside the main database. Sync them via a content-addressable store or a dedicated media sync service.
Testing an Offline-First Application
Testing is harder when you have to simulate network failures. Here are practical approaches.
- Use a network proxy tool like mitmproxy or Clumsy. These tools can simulate packet loss, high latency, and complete disconnection. Run your integration tests through them.
- Write unit tests for conflict resolution logic. Create test cases where two devices modify the same record with different values. Verify that your merge function produces the expected result.
- Automate sync round-trip tests. Simulate creating a record offline, reconnecting, and verifying that the server and other clients receive the correct state.
- Test with real devices on marginal networks. Go to a basement, a subway station, or a rural area. Nothing beats real-world testing for finding edge cases.
Building for the Future of Local-First
The offline-first movement is growing. New protocols like the Local-First Web (LFW) and standards around CRDTs are making it easier to build interoperable offline systems. As edge computing and IoT devices proliferate, the ability to process data locally and sync later becomes even more critical. Developers who master these patterns today will be ahead of the curve tomorrow.
Your Next Steps as an Offline-First Architect
Start small. Pick one feature in your current application that would benefit from offline support. Implement a local database, a write-ahead log, and a basic sync mechanism. Measure the improvement in response time and user satisfaction. Then expand from there. The tools and patterns are mature enough in 2026 that you can build production-grade offline experiences without reinventing the wheel. Your users will thank you when their work survives the next dropped call or dead zone.